Using Oracle Incremental Merge

This article outlines the Incremental Merge feature of the Oracle database and it’s intended usage.  This article also addresses how 3rd party products have been built upon this feature of Oracle, delivering database cloning capabilities (also known as copy data management) as well as backup/recovery solutions.  Finally, this article will cover how Oracle addresses such requirements using native features of the Oracle database in a Maximum Availability Architecture (MAA) configuration rather than relying on the Incremental Merge feature.

What is Incremental Merge?

The Incremental Merge capability of  the Oracle database refers to the ability to create a copy of a database and periodically update that copy by merging incremental changes into that copy.  In short, Incremental Merge is comprised of the following capabilities:

  • Image Copy Backup of Oracle Database
  • Incrementally Updating the Image Copy
  • Archive Redo Log Management
  • Restore and Recovery from Image Copy
  • Duplicate Database from Image Copy
  • Switch to Copy Feature

Incremental Merge involves a single copy of the database as-of a single point in time.  The database is drawn forward on the change timeline by applying incremental backups.  Archived redo logs spanning the duration of backup execution are required to de-fuzzy the contents of the resulting image copy (see note1).  The resulting image copy can be used for restore and recovery, duplicating databases, and switching a database to the image copy.

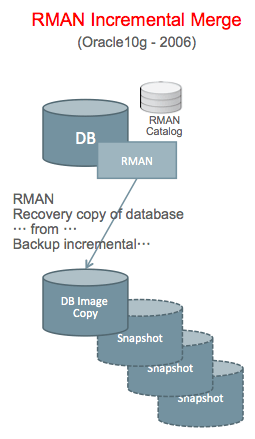
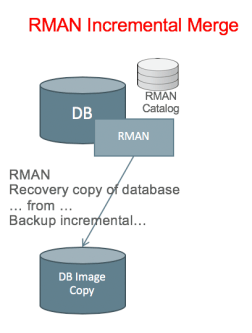
The following diagram shows how RMAN is used to apply the changes from an incremental backup to an image copy of the database.
Screen Shot 2018-11-07 at 4.52.51 PM

Note 1: For the purposes of this article, we assume customers are using HOT backup.  Customers seldom use COLD backups, where the database is shut down during the backup.  Database backups (including image copy and incrementals) should be considered “fuzzy” if the database was online and active during the backup.

Intended Usage of Incremental Merge

The Incremental Merge feature was intended to be used in a transient manner for specific tasks such as:

  • Cloning Databases to DEV/TEST
  • Upgrading database/storage hardware
  • Instantiating Data Guard Standby

The Incremental Merge feature was not developed to be an operational backup/recovery capability.  Incremental Merge maintains a single image copy as of a single point-in-time, whereas backup/recovery typically requires recoverability over a much longer window of time such as weeks or months.  One solution to this problem is DELAYING the apply of incremental backups to allow as much as 7-10 day of recoverability, while most enterprises require recovery windows for 30 days or longer.  Oracle recommends using a fully functional backup/recovery solution (meeting the business mandated recovery window) for the use-cases above instead of using Incremental Merge.

3rd Party Vendor Solutions

Several 3rd party vendors have developed solutions based on the Incremental Merge feature including the following:

  • Actifio
  • Rubrik
  • Delphix
  • NetBackup Co-Pilot

Some of these vendors go beyond the intended use of Incremental Merge as a transient data copy capability and recommend using it for operational backup/recovery.  Storage snapshots are used to provide multiple restore-points, whereas Incremental Merge natively provides a single restore point.

Avoid Products that use Reverse Engineering

Customers should avoid using any 3rd party products that use undocumented interfaces or reverse engineer features of Oracle such as internal Oracle data structures, including the contents of Oracle RMAN Backups.  Oracle may modify those structures and product behavior without notice at anytime in any version, release or even with a simple patch.  Customers should evaluate 3rd party products to determine if  undocumented interfaces are being used or if the vendor has reverse engineered the Oracle database.

Custom Built Solutions

It is important to note that customers have also built custom-scripted Incremental Merge solutions using these same core Oracle database features for creating image copy backups and updating them incrementally.  Customers have used both SAN (block storage) as well as NAS storage (such as Oracle’s ZFS storage) to build these Incremental Merge solutions.

Adding Snapshots to Incremental Merge

Incremental Merge provides a single copy of the database as-of a single point in time, which fits the intended use-cases of building database for DEV/TEST, for hardware migration, or instantiating Data Guard Standby databases.  A single copy of the database is created on a different set of hardware, and the database is incrementally updated until it reaches the desired point.

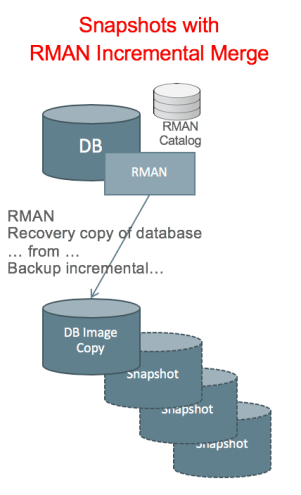
The following diagram shows how snapshots are added to incremental merge to provide multiple restore points.
Screen Shot 2018-11-07 at 4.54.05 PM

Some 3rd party vendors add storage snapshots to the Incremental Merge solution to allow multiple restore points so it can serve as a backup/recovery solution.  Some customers have also built custom scripted solutions following this model as well.  The resulting snapshots can then be cataloged with RMAN to allow database recovery using those snapshots.

Critical Solution Design Issues

The Incremental Merge solution presents several issues where process must be executed correctly to avoid corruption.  Customers should be aware of the following issues when implementing an Incremental Merge solution:

  • Timing of Merge Process
  • Timing of Snapshot Execution
  • Timing of Redo Log Archival
  • Handling of Archived Redo Log Backups
  • Recovery point required to de-fuzzy Image Copy

Timing of the merge process and snapshot execution is critical to avoid corruption of snapshot copies.  Incremental Merge was not designed for use with snapshots, and does not include the “snapshot optimization” feature of the Oracle database itself.  Snapshots cannot overlap with the Incremental Merge process, or corruption will result.  It is also important to note that the resulting Image Copy is not consistent and needs some amount of redo applied to make it consistent.  The necessary change-vectors to de-fuzzy the backup must be externalized into the archived redo and backed-up.  The recovery point is also critical  to avoid “file needs more media recovery” errors.

Oracle Error: “File Needs More Media Recovery”

Incremental Merge is a “fuzzy” backup that needs recovery to be consistent, which means not corrupt.  Most experienced Oracle DBAs are familiar with the Oracle error “file needs more media recovery”, which indicates the backup is corrupt (“fuzzy”) and can occur in several circumstances with different Oracle error numbers as follows:

  • ORA-01113
  • ORA-01194
  • ORA-01195
  • ORA-19901
  • ORA-01143

In all of these cases, redo logs are required to de-fuzzy the database and make it consistent before it can be opened for use.  Recovery into the middle of a fuzzy range requires restoring a PREVIOUS backup and rolling forward.  Image copy backups should be treated as fuzzy if taken while the database is up and running.  Proper redo log handling is critical to the Incremental Merge process because redo logs are required to de-fuzzy the image copy.

Managing the Archived Redo Log Stream

The Incremental Merge feature deals with handling of DATA blocks only, and does not address how the redo stream is handled.  Redo is critical to successful operation of the Incremental Merge feature.  Proper redo handling is even more critical when used in conjunction with snapshots.  Oracle recommends switching, archiving, and backing up the redo log so that change-vectors required to de-fuzzy the image copy are included in the backup.

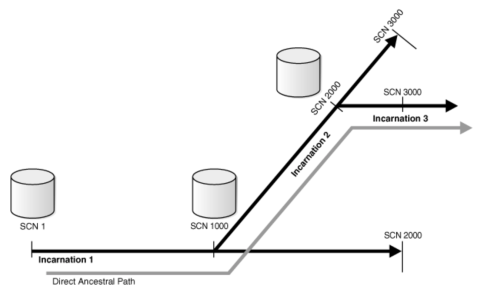
The following diagram (from the Oracle RMAN documentation) shows how the redo log stream records database incarnations, which are used during database recovery.
Screen Shot 2018-11-07 at 4.57.02 PM

Oracle also recommends NOT including the archived redo stream in a snapshot, and certainly not in the same snapshot that contains the Image Copy.  Redo log change-vectors generated AFTER the incremental backup are required to de-fuzzy the database.  Database recovery also requires access to ALL available incarnations of the redo stream to properly navigate incarnations as shown in the diagram above.

Data Loss During Recovery

Archived redo is typically 20 minutes or longer behind the current changes in the database depending on the log switch interval.  The image copy will be as much as 24 hours behind current, while redo backups will be at least 20 minutes behind current.  Therefore, customers should expect anywhere from 20 minutes to 24 hours of data loss (loss of transactions) when using Incremental Merge for backup/recovery.

Online REDO logs are re-used in a circular fashion.  Archived redo is sequential and provides a record of changes over the course of time.
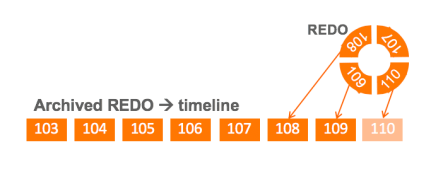
Screen Shot 2018-11-12 at 1.08.17 PMThe structure of Oracle redo also includes incarnations (as discussed earlier), with each incarnation representing different branches of the timeline.  In the diagram above, the latest transactions are contained in log sequence 110, which is not yet available in the archived redo.  Those transactions will be lost in an Incremental Merge solution.  Customers should consider Oracle Data Guard or the Zero Data Loss Recovery Appliance (ZDLRA) to eliminate loss of transactions.

Does Switch to Copy = Instant Recovery?

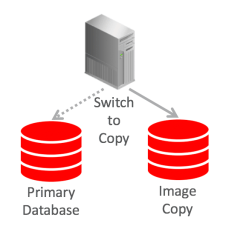
Oracle provides a feature known as Switch to Copy, which allows a database to be switched to an Image Copy instead of using Media Recovery.  Some 3rd party vendors have described this as “instant recovery”, which is not correct.  Switch to copy is a SWITCH operation that can be used in place of restore as shown below.
Screen Shot 2018-11-12 at 1.19.32 PM

Switch to copy involves pointing Oracle at a different copy of the database, which is similar to a restore operation, whereas database recovery is the act of applying redo logs.  At the end of the switch to copy command, the image copy will still need recovery, which is not instantaneous.  As discussed earlier, the image copy will normally be as much as 24 hours behind current, and redo logs will be at least 20 minutes behind current.  Any Image Copy taken HOT will also need some amount of recovery (log apply) to make it consistent as well as to reach the desired point-in-time.

Again, recall that Incremental Merge does not include provisions for handling the redo logs, so switch to copy involves data loss (loss of transactions).  Depending on the intended usage, this capability isn’t usable if the Image Copy resides on lower tier (slower) storage.  The concept of “instant recovery” implies that the database is usable and will provide the same level of service that users expect of the production database.

Switching to Equivalent Storage

The switch-to-copy feature should only be used with storage that meets performance expectations.  Production databases typically cannot operate on a lower tier of storage than used for production.  It is important to note that switch-to-copy using any 3rd party storage is not compatible with Exadata and is not supported.

Oracle recommends customers use Data Guard rather than switch-to-copy.  Data Guard is more widely used and avoids the data loss issues inherence with switch-to-copy as outlined above.  Data Guard Standby databases can also be placed on equivalent storage as the production database to meet end-user performance expectations.

Resource Stealing

Incremental Merge steals resources from the source databases including CPU, memory, network I/O, and disk I/O resources.  The same Oracle software version must be used to APPLY incremental changes to the image copy, and the most common method is to simply use the source database to merge incremental changes into the image copy.  Resource Stealing needs to be considered in system capacity planning and customers need to be aware of performance impact from resource stealing.  Oracle Data Guard does not rely on resource stealing, and places minimal overhead on source servers and network.

Oracle Data Guard

Oracle Data Guard provides the ability to instantiate a copy of a database and update that copy either synchronously or asynchronously via the redo log stream.  The following diagram shows the basic Data Guard configuration including the observer capability known as the Data Guard Broker.
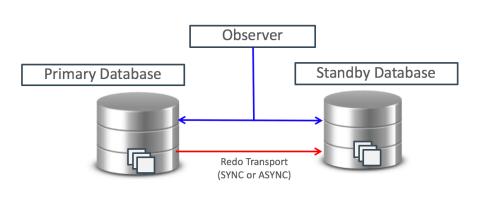
Screen Shot 2018-11-12 at 10.54.52 AM

In addition to keeping a standby database in close synchronization with the primary, Data Guard also provides the ability to use a TIME DELAY, which is functionally similar to Incremental Merge with a different update mechanism.  Data Guard advances a copy of a database forward on the timeline of changes by using the REDO log, whereas Incremental Merge updates a copy of a database using incremental backups.

Using Data Guard for this case assumes the use of ARCHIVELOG mode, and FORCE LOGGING is required to eliminate gaps caused by use of NOLOGGING operations.  Some legacy hardware configurations might not offer sufficient performance for this configuration, while Exadata has proven to deliver the performance necessary for fully logged databases even with high transaction volumes as well as high volume ETL processing in Data Warehouse environments.

Oracle Snapshot Standby & SPARSE Disk Groups

Oracle’s Snapshot Standby is a critical feature for creating DEV/TEST copies of databases from production.  The process is fully automated through Oracle Enterprise Manager (OEM), Data Guard Broker, and SQL Plus.  The Snapshot Standby is created from a Data Guard Physical Standby, and can be reverted back to Physical and re-synchronized with the production database.

Once a snapshot standby is created, Oracle’s SPARSE Disk Groups also provide the ability to create multiple thin-provisioned (SPARSE) clones from a Snapshot Standby.  Oracle RMAN also allows SPARSE backups, extending the thin-provisioning capability into the backup solution as well.
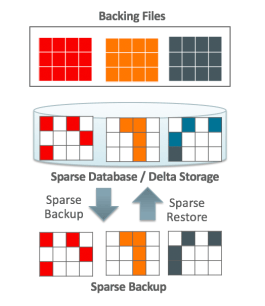
Screen Shot 2018-11-12 at 12.31.09 PM

Database Recovery with Incremental Merge

The Incremental Merge process involves IMAGE COPY backups that are typically fuzzy copies needing redo to be applied to make them consistent.  There are essentially 4 database recovery scenarios that any backup/recovery solution needs to support as follows:

  1. Repairing Physical Corruption
  2. Point-in-Time Database Recovery
  3. Point-in-Time Object/Table Recovery
  4. Recovery Based Cloning

Oracle’s RMAN (Recovery Manager) tool is used to perform recovery of Oracle databases in all of the use-cases above.  Some 3rd party solutions also include interactive tools or APIs that layer on top of the functionality provided by Oracle.  In this section, we will cover this from the standpoint of the RMAN tool that most DBAs are familiar with.

Repairing Physical Corruption

The first use-case for RMAN addresses the need to repair databases if physical corruption occurs, which is also referred to as “recover to current” or recovering the database to the current (or latest) transaction.  RMAN provides 3 levels of physical database repair as follows:

  • Block Media Recovery
  • Data File Restore & Recovery
  • Database Restore & Recovery

Block Media Recovery can uses a FULL or LEVEL0 backup, or can use a Virtual Full on Oracle’s Recovery Appliance (RA). Redo logs are applied to recover the block(s) forward after the block is restored from the FULL, LEVEL0 or RA Virtual Full.  Block recovery also works with Oracle Data Guard as shown below.
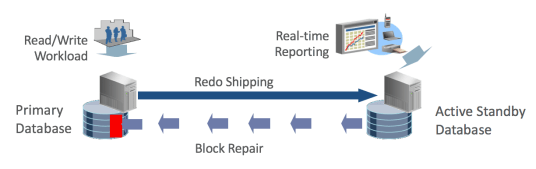
Screen Shot 2018-11-12 at 12.41.36 PM

Point-In-Time Database Recovery

While the Recovery Advisor can detect and automatically launch repair actions when physical corruption is encountered, it’s not possible to automatically evaluate “logical” corruption caused by factors such as application failures.  For example, an application might be defective, or a user might delete data by mistake.  Those types of failures simply cannot be detected by the database.

Point-in-Time Object/Table Recovery

In some cases, logical corruption might impact only a single or a few tables within the database.  Rather than recovering the entire database to a prior point-in-time, it might be desirable to recover only those tables effected by the wayward application or user.

Incremental Merge with snapshots was useful in previous releases to facilitate table recovery.  However, Oracle12c and above offers the ability to recover tables using backups, as well as the ability to REMAP the table into a different schema as shown below:
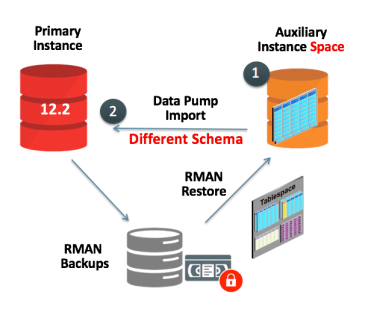
Screen Shot 2018-11-12 at 11.15.50 AM

Tables are often recovered to a previous point in time due to application failures or end-user errors.  Placing the recovered table in a different schema allows a developer or user to examine the data to determine what changes (if any) should be made to the production data.  This process has become much simpler in Oracle12c due to the feature outlined above.

Validation Of Image Copy Backups

The Incremental Merge process effectively validates the blocks that have changed, but un-changed blocks are never validated.  Oracle recommends periodically executing the RMAN RESTORE command with the VALIDATE option to ensure integrity of Image Copy backups.  Oracle’s Zero Data Loss Recovery Appliance provides automatic validation of backups without using resources of the database server, and without manual data validation scripts.

Conclusion

Incremental Merge is a feature of the Oracle database that was developed for transient use such as creating database clones for TEST/DEV, instantiating Data Guard standby databases, and for migrating to new hardware.  Some 3rd party vendors have used the Incremental Merge feature to replicate capabilities that are provided natively as part of the Oracle database.  This article outlined how native features of the Oracle database provide many of the capabilities that Incremental Merge solutions have provided in previous releases.  Oracle recommends customers follow the Maximum Availability Architecture (MAA) reference architectures to meet business goals.

References:

Maximum Availability Architecture: http://www.oracle.com/goto/maa

ZDLRA: https://www.oracle.com/engineered-systems/zero-data-loss-recovery-appliance/


Oracle Recovery – Regarding Range Gaps

My team and I have been digging deep into Oracle database recovery lately, and we’ve noticed that some mistakes by administrators can jeopardize recoverability.  Oracle’s Recovery Manager (RMAN) product does a great job of catching issues, but it’s still possible to induce these failures.  This blog posting should help to explain how these problems occur and what can be done to correct problems with what we call “range gaps” in the recovery stream.

Restore and Recovery Range Gaps can be induced through improper use of Oracle’s Recovery Manager (RMAN) as well as through improper management of backup data stored in a Media Manager or other backup target.  Oracle’s Zero Data Loss Recovery Appliance (ZDLRA) will prevent these problems, or will detect, report and allow them to be corrected as outlined below.  Let’s start with a bit of terminology to set the stage.

Terminology

Restore Range Gaps – Restore Range Gaps refer to gaps in recoverability of data file backups as part of a full plus incremental backup strategy using a combination of LEVEL0 and LEVEL1 backups.  Lost Differential Incremental (LEVEL1) backups will essentially invalidate subsequent differential incremental backups.

Recovery Range Gaps – Recovery Range Gaps refer to gaps in recoverability of data due to lost ranges of redo logs.

Ordering Waits in ZDLRA – Oracle’s Zero Data Loss Recovery Appliance (ZDLRA)  will place backup pieces into an Ordering Wait status when Restore Range Gaps are detected.

Fetch Archive Log – When Real Time Redo Protection is used with ZDLRA, Recovery Range Gaps can be reconciled by the applications through the Fetch Archive Log (FAL) process.

Backup Polling – ZDLRA supports use of a “polling location” for ingesting backups.  RMAN backups written in Disk Format can be directly ingested into ZDLRA through the polling feature.

How Restore Range Gaps Occur

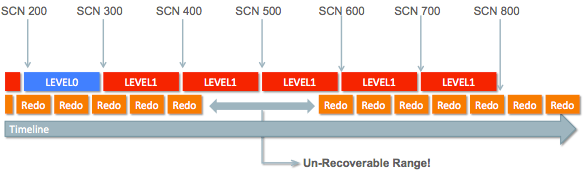
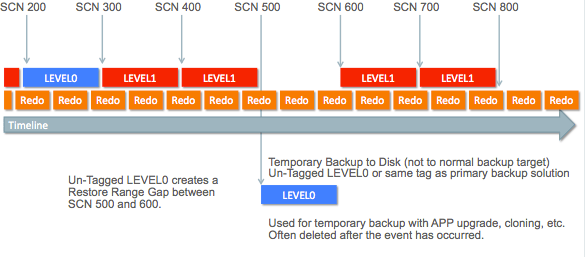
In a non-ZDLRA environment, gaps in the Restore Range can be induced through improper use of RMAN.  The following example occurs when a DBA performs a supplementary LEVEL0 backup to disk at SCN 500 in the following diagram:

Screen Shot 2018-04-12 at 1.02.54 PM

In the example above, the LEVEL0 is either un-tagged or uses the same tag as backups sent to the primary backup solution.  This means the LEVEL0 is part of the backup, even though it has been sent to a different location.

Restore Range Gaps in ZDLRA

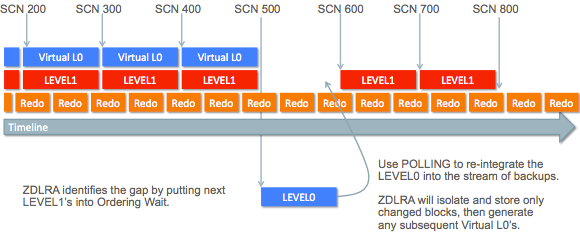
ZDLRA is susceptible to the same mistake as shown in the previous section, but ZDLRA will detect the gap and allows the gap to be filled.  The example below shows that Virtual L0 backups stop being generated due to the Restore Range Gap.

Screen Shot 2018-04-11 at 6.04.45 PM

Gap Detection – ZDLRA will identify Restore Range Gaps, and will place subsequent backup pieces into Ordering Wait status.  The above diagram shows a LEVEL0 backup being taken to an auxiliary location such as a space on disk.  The resulting LEVEL0 backup includes changed blocks that are critical to database recovery.  Generation of Virtual L0 backups will terminate when a Restore Range gap is detected.  The LEVEL1 backups following the range gap will be placed into Ordering Wait state until the gap is resolved.

Gap Resolution – ZDLRA is able to correct this problem by simply “polling” the LEVEL0 into the Delta Store.  The LEVEL0 backup contained un-changed blocks, but also contains the changed blocks require to fill the Restore Range Gap.  ZDLRA will de-duplicate the data by simply discarding the un-changed blocks.

Intermediate Recovery Range Gaps

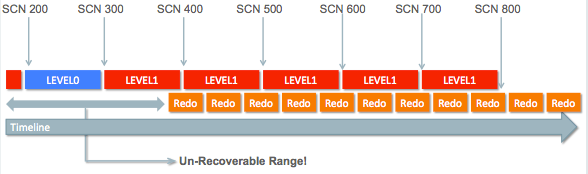
Recovery Range Gaps occur due to improper management of redo logs.   Recovery Range Gaps represent an unrecoverable range in the timeline, meaning the database simply cannot be recovered into that gap.  The example below shows a Recovery Range Gap approximately from SCN 425 to SCN 575.

Screen Shot 2018-04-12 at 11.06.13 AM

Existence of the associated LEVEL1 backups mean that the database can be recovered to points prior to SCN 425, or after SCN 600, but cannot be recovered to points between SCN 425 and SCN 600.  Recovery Range Gaps like this occur in one of 3 ways:

  • Deletion of Redo on Source Prior to Backup
  • Failed Backup Processing
  • Deletion of Redo on Backup Target

Redo logs are stored on each database server, either in an Log Archive Destination, or in a Fast Recovery Area. The Log Archive Destination (specified by the LOG_ARCHIVE_DEST_n parameter) configuration is supported for backward compatibility.   Customers should implement the Fast Recovery Area feature instead of using the older Log Archive Destination configuration.

The Fast Recovery Area simplifies management of redo logs and is designed to prevent improper deletion of redo that can jeopardize recoverability.  For more information on the Fast Recovery Area feature, please see the Oracle database documentation here.

The Fast Recovery Area allows DBAs to manage redo according to policies, and prevents deleting redo before it is backed-up.  Redo is marked as eligible for deletion only after being backed-up.  Administrators can still override this setting and delete redo even if it hasn’t been backed-up, but this will create a Recovery Range Gap.

We have seen Recovery Range Gaps generated due to failed backup processing.  Some 3rd party backup products have been known to NOT send error messages to RMAN even though the backup data was not saved.  One method to detect such problems is to execute the following RMAN command:

RMAN> CROSSCHECK BACKUP

The crosscheck command will check contents of the RMAN catalog against 3rd party media catalog and report any missing data.

Trailing Recovery Range Gaps

Trailing Recovery Range Gaps result in the same problem as described above, but are more likely to be caused by improper deletion of redo on the backup target instead of on the source.  The following diagram illustrates this type of failure:

Screen Shot 2018-04-12 at 12.32.29 PM

The above example indicates that REDO is being deleted too quickly even though it is required for recoverability.  Media recovery cannot be performed in any range prior to SCN 400 in the above example.  If all redo prior to SCN 380 has been deleted, this seems to indicate an improper deletion policy on the backup target.

Depending on change rates, redo logs can represent significant space consumption.  Redo logs tend to be less compressible, but simply will not de-duplicate because each redo log contains unique (non-duplicate) data by definition.

ZDLRA Resolves Recovery Range Gaps

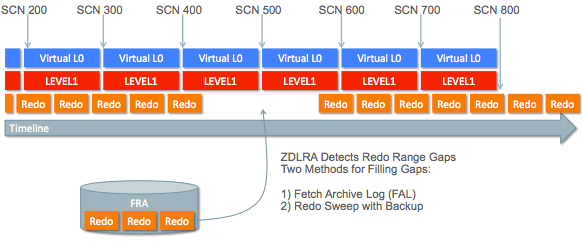
ZDLRA is able to automatically resolve Recovery Range Gaps, and will ALERT when Recovery Range Gaps are detected.  The following diagram shows this capability:

Screen Shot 2018-04-12 at 12.38.42 PM

ZDLRA will detect Recovery Range Gaps and fill those gaps using the FAL (Fetch Archive Log) process, which reaches back into the FRA (Fast Recovery Area) of the protected database.  For databases not configured for Real Time Redo protection, any un-transmitted redo will be send to ZDLRA using the following backup command:

RMAN> BACKUP DATABASE ...
      PLUS ARCHIVELOG NOT BACKED UP...

The standard RMAN backup command for use with ZDLRA always includes backup of archived redo that has not been backed-up, even when Real Time Redo Protection is enabled.  This configuration provides a failsafe that ensures the redo will be swept from the FRA regardless of whether Real Time Redo Protection is functioning or not.

Conclusion

Range Gaps occur in both the “restore” stream as well as in the redo log or “recovery” stream of data sent to a backup target.  Any experienced database administrator knows that databases cannot be recovered to SCN’s that reside within a range of redo that has been lost.  It’s important to also know that loss of incremental LEVEL1 backups will create a similar gap in the Restore Range represented by a set of LEVEL0 and LEVEL1 backups.  When such Range Gaps occur, database administrators won’t know these problems exist unless a database recovery is attempted.  Oracle’s Zero Data Loss Recovery Appliance (ZDLRA) will identify and alert when Restore & Recovery Range Gaps occur.  These gaps can also be corrected using some of the unique features of ZDLRA, preserving database recoverability and meeting business needs for data protection.


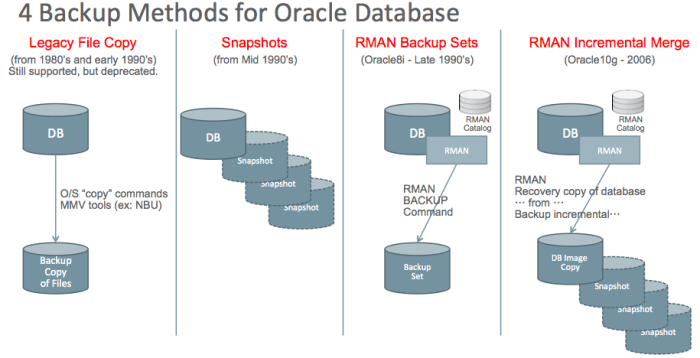
4 Oracle Backup Methods

While there is a vast array of backup products on the market that support Oracle, all of these solutions implement 1 of 4 available methods as shown below:

Screen Shot 2018-02-27 at 2.42.02 PM

The 4 backup methods are categorized according to the method used to manipulate the data underlying the Oracle database.  This blog post will outline each of these 4 methods and will explain how Oracle’s Zero Data Loss Recovery Appliance (ZDLRA) is distinctly different from these 4 methods.

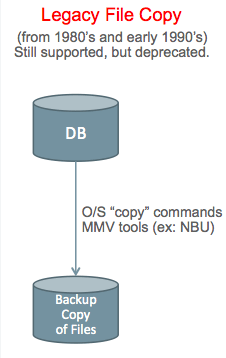
Legacy File Copy

As the name implies, Legacy File Copy is an older method for backing up Oracle databases that dates from the earliest days of Oracle.  I am covering this solution primarily for completeness and because it’s still used today (although rarely).  This method involves using tools such as O/S “copy” commands such as “cp” on Unix/Linux, as well as 3rd party tools such as MMV (Media Manager Vendor) utilities to backup database files directly.

Screen Shot 2018-02-27 at 4.41.59 PM

Cold Backup refers to making copies of database files while the database is in a shutdown state.  The database must be shutdown cleanly using SHUTDOWN NORMAL, SHUTDOWN TRANSACTIONAL, or SHUTDOWN IMMEDIATE prior to copying the underlying files.

Hot Backup refers to copying database files while the database is running.  Taking a hot backup using legacy file copy requires use of BEGIN/END BACKUP commands at the table space level or for the entire database at once.  The DBMS generates extra redo logging when these commands are used, so

Redo log handling is absolutely critical in legacy file copy backup.  The first challenge is to NOT backup files while they are being written by the ARCH (redo log archiver) process.  The next challenge is to NOT delete redo logs unless they have been backed-up.  The final challenge is to ensure all redo associated with the backup has also been backed-up so you have a complete set of redo to “de-fuzzy” the backup.  There are critical timing issues down to the microsecond level that can make the difference between success and failure.  Improper handling of redo was a major source of backup corruption in the days prior to RMAN.

Multi-Threading is extremely difficult in a legacy file copy solution, which ultimately limits the size of database the solution can support.

The vast majority of Oracle customers abandoned the old Legacy File Copy solution many years ago, but some customers continue using these solutions.  Most customers migrated to RMAN when it was introduced, and a small number of customers use storage snapshots as discussed in the next section.

Snapshot Backups

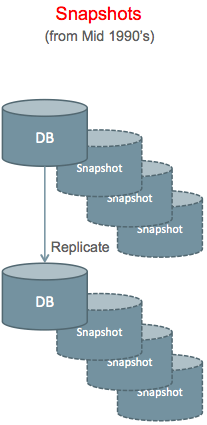
Snapshots Backups are typically implemented in the storage layer or disk array.  Snapshots were originally introduced in the late 1990’s, and were a good alternative to legacy file copy solutions, but have some critical complexities that we will explore in this section.

Screen Shot 2018-02-27 at 4.56.13 PM

Snapshots provide a virtually instantaneous copy of files on storage, which eliminates some of the complexity involved with multi-threading required for large database backups using the Legacy File Copy method.  Snapshots seem quite simple and effective on the surface, but the reality is less attractive.

Snapshot Backups are NOT Recommended

To be clear, we do NOT recommend using snapshots for backups.  Snapshots should be used for transient fallback on production systems, or for storage efficiency purposes on DEV/TEST systems.  Snapshots alone are not proper backups and should be used only in conjunction with storage replication or an auxiliary backup method.

Replicated Snapshots

Snapshots stored within the same storage as the database are not proper backups, especially if they are thin-provisioned (pointer-based) snapshots.  Loss of ALL data contained in the storage array (database and backups) is possible if everything is contained in a single disk array.  Replication is required in order to have a viable backup solution using snapshots.  The above diagram shows data and snapshots that are stored locally, as well as a replicated copy of the full storage and all snapshots.

Replicating Corruption is a danger with any bit-copy storage replication solution.  If the system suffers a ransomware attack, the encryption of data is dutifully replicated to the secondary site, resulting in encryption of BOTH sites.

Full Replication of storage including the database and all snapshots provides the best protection, but at higher cost.  In configurations where the database and all snapshots are maintained at both sites, local snapshots can be used for recovery as long as the failure doesn’t impact the entire disk array or the “base” that snapshots reference.

Snapshots at Replica Only provides good protection at lower cost because the space required for snapshots is only incurred at the replica site.  Using those snapshots for recovery on the primary site requires copying data back across the network.

ASM (Oracle’s Automatic Storage Management) needs to be used with care in conjunction with any storage replication.  ASM re-balance operations are a particular concern, since large numbers of blocks are “modified” at the storage layer, even though the affected blocks haven’t changed from the database perspective.  ASM re-balance results in massive numbers of blocks being replicated across the network.

Auxiliary Backup

Some customers implement an “auxiliary backup” in conjunction with snapshots rather than using storage replication.  One customer referred to this as a “snap & mount” solution because they used SAN (Fiber Channel) storage, and the file systems would be mounted on another system after the snapshot.  The second system would be used to run a backup of the snapshots.  Running auxiliary backups is simpler with NAS storage, since the secondary system does not need to be as closely aligned with production from the standpoint of versions, patching, etc.

Screen Shot 2018-02-28 at 8.17.53 AM

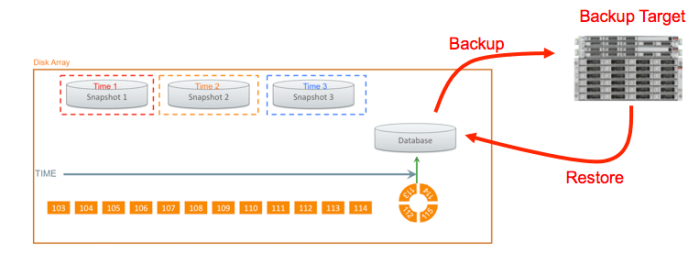
The diagram above shows storage snapshots contained within a disk array, with an auxiliary backup target (either tape or disk).  The database can be reverted to any of the snapshots within the disk array, or restored from the auxiliary backup target.  Setting end-user expectations for MTTR should be based on the worst-case, which is restoring from the auxiliary backup.  See the section on MTTR for more discussion of this topic.

The remainder of this section assumes that snapshots are used in combination with replication or an auxiliary backup solution.

Crash Consistent Snapshots

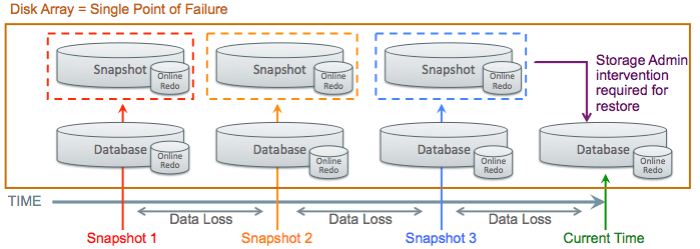
The simplest form of snapshot backups is the Crash Consistent Backup.  The configuration is relatively easy to understand, and relatively easy to operate.  However, this is what I call a “guaranteed data loss” solution as shown in the following diagram.

screen-shot-2017-01-03-at-1-00-37-pm

The above diagram shows a database advancing through time, and snapshots being taken at 3 points (red, orange, and blue snapshots).  The entire disk array is a single point of failure, so some sort of replication is required.

Oracle’s Snapshot Requirements must be met for a valid Crash Consistent Snapshot.  The snapshot solution must provide the following attributes:

  • Consistent across all files or disk volumes
  • Must preserve write ordering

Snapshot technologies that do not meet these criteria will not produce a crash consistent image of the database.  Please refer to the section on inconsistent snapshots for more detail.

NOARCHIVELOG Mode should be used in a Crash Consistent Snapshot solution, and the online redo logs MUST be included in the snapshot.  The entire database, online redo logs, and control files are all reverted to the same point in time.  Oracle will automatically run through crash recovery, rolling back any in-flight transactions.   It is not possible to recover to any points between snapshots in this configuration, meaning data loss (lost transactions) will occur.

Recoverable Crash Consistent Snapshots

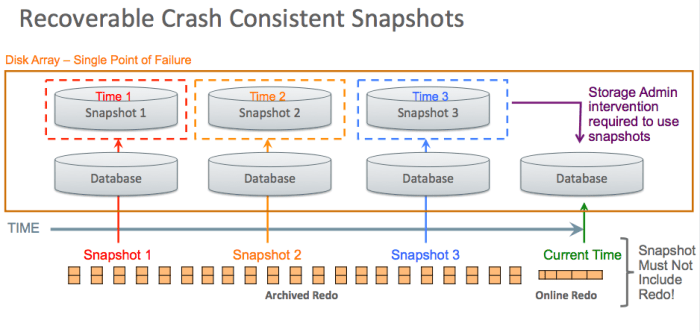
Crash Consistent Snapshots can be made Recoverable, allowing for recovery beyond the instant a snapshot was created, or recovering to an SCN between snapshots.  The following diagram shows how crash consistent snapshots can be made recoverable by keeping REDO (online and archived REDO) separate from snapshots of the datafiles.

Screen Shot 2018-02-28 at 8.23.34 AM

In the above example, the database can be reverted to snapshot #1, then recovered forward using the redo logs.  Redo (and control files) are kept separate from the snapshot containing datafiles, which is what enables recovery.

Online Redo and Controlfiles must be kept at “current” or at a later point in time from the database to allow media recovery.  Transactional changes to the database are stored in the range of online redo as well as the stream of archived redo that precedes the online redo range.

Archived Redo Retention must reach as far back as the time of the snapshot used for recovery.  There is no reason to revert the stream of redo to an earlier point, since the redo represents a continuous stream or timeline.  The database can be recovered to any SCN along the timeline, rolling forward from the point of any snapshot.

Snapshots (or Restore Points) on Redo/FRA can be used to protect against administrator error, viruses, ransomware attacks, etc.  The Oracle database redo log is a write-ahead log, and log files are never over-written.

The High Write SCN determines the lowest point in time that can be used for recovery with any specific snapshot.  Oracle’s “snapshot optimization” feature was developed in conjunction with storage vendors.  The storage writes a timestamp into the snapshot, and that timestamp is then used in the RMAN commands using the SNAPSHOT TIMESTAMP clause.

The Database Scanner utility can be used with older versions of the Oracle database using storage that doesn’t support the Snapshot Optimization Feature.  The utility is used to scan the entire database looking for blocks with the highest written SCN in the database.  That SCN defines the point the database must be recovered to at minimum.

File Needs More Media Recovery is the error that will occur if the database is not recovered to a point after the high-write SCN.  A previous snapshot will have to be used in that case to hit the desired SCN.  The choice is to use the database scanner (a full scan of every block in the database) or trial and error will show whether the chosen SCN is high enough.

Inconsistent Snapshots

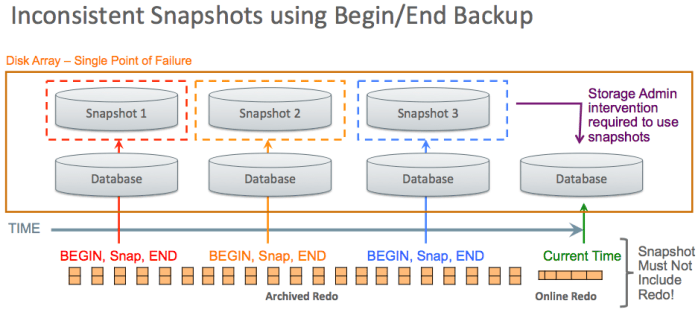
Some older snapshot technologies were not able to meet the data consistency requirements of Oracle.  All data structures of the Oracle database (datafiles, controlfies, redo logs, etc.) must be snapped at the SAME instant in time.  The order of writes also must be preserved to ensure data integrity.  Customers need to be aware that some NEW snapshot technologies cannot meet these data integrity requirements, so the old “inconsistent snapshot” method has to be used.  The following diagram shows how inconsistent snapshots can be used as an Oracle database backup method.

Screen Shot 2018-02-28 at 9.06.42 AM

As noted previously, the disk array itself is a single point of failure.  Loss of the disk array means loss of the database and all snapshots.  There are specific commands that can be run on most disk arrays that will jeopardize the database and all snapshots.  Customers should be sure to use storage replication or an auxiliary backup method with snapshot technologies.

BEGIN/END BACKUP commands must be used in conjunction with the snapshot, either at database or tablespace level.  Database redo logging increases dramatically after executing BEGIN BACKUP.  The excessive redo log rates continue until END BACKUP is executed.  The BEGIN BACKUP command does not “quiesce” the Oracle database.  The command causes the Oracle database to generate additional information into the redo log to “defuzzy” the backup and resolve any “split block” conditions caused by the inconsistent snapshot.

Online Redo, Archived Redo, and Controlfiles must be kept separate from the datafile snapshots as shown in the above diagram.  If those data structures are placed into a separate snapshot, that snapshot must be Crash Consistent.

Archived Redo Retention (as with Recoverable Crash Consistent Snapshots) must reach as far back as the time of the snapshot used for recovery.  There is no reason to revert the stream of redo to an earlier point, since the redo represents a continuous stream or timeline.  The database can be recovered to any SCN along the timeline, rolling forward from the point of any snapshot.

MTTR from Snapshots

One primary rule with MTTR (Mean Time To Repair) calculations is to “plan for the worst, but hope for the best”.  Recovery using a local snapshot is obviously the best case, while recovery using a remote replica or auxiliary backup will provide the worst case recovery.

One customer I was involved with used snapshots as the primary method of recovery, and set expectations with the business that recovery would be done in less than 1 hour.  This customer had a 48TB database with auxiliary backup using EMC’s Data Domain.  Restore from Data Domain ran at 1TB/hour, which means 48 hours for restore time alone for their 48TB database (restore is only part of the recovery process).  The IT team was faced with business expectation of 1 hour recovery, but 48 hours of restore time.  In the end, this customer suffered a 4-day outage due to inadequate secondary solution and a primary solution that was high risk (snapshots are not proper backups).

Snapshot Recovery is Manual

All recovery from snapshots is manual and requires coordination between DBA and Storage Administrator.  Features such as Oracle’s Recovery Advisor cannot be used because all of the backups (snapshots) are done outside of Oracle’s control.  Some 3rd party vendors offer specialized tools to aid in recovery using snapshots.

RMAN Backup Sets

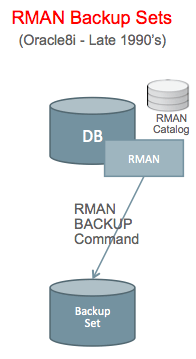
Solutions based on RMAN Backup Sets are the most commonly used method for backup & recovery of Oracle databases.  I would estimate that greater than 80% of Oracle databases are protected using RMAN Backup Sets.  The vast majority of Oracle customers also implement systems according to ORacle’s Maximum Availability Architecture (MAA) guidelines, and RMAN Backup Sets are a critical component of MAA.

Screen Shot 2018-02-28 at 10.18.42 AM

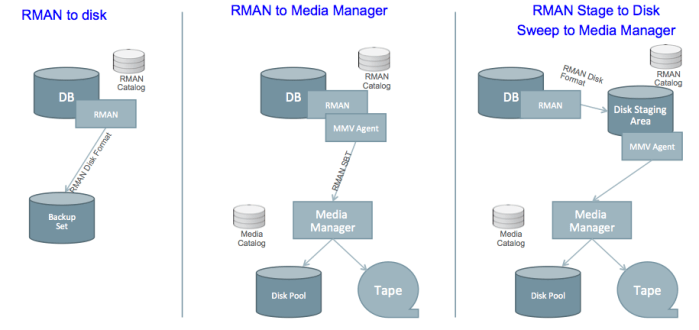
RMAN was introduced in Oracle8i with the Backup Set capability in the late 1990’s, and Backup Sets have become the most widely used method for backup/recovery of Oracle databases.  There are 3 implementations of RMAN Backup Set configurations as follows, using backup to disk, backup to media manager, and staging areas as follows:

Screen Shot 2018-02-28 at 10.31.41 AM

RMAN backup sets have a different format when written directly to disk as compared to SBT (Serial Backup to Tape) format sent to a Media Manager.  The Media Manager might be configured to use a “disk pool” to store the data, but it’s still in SBT format.

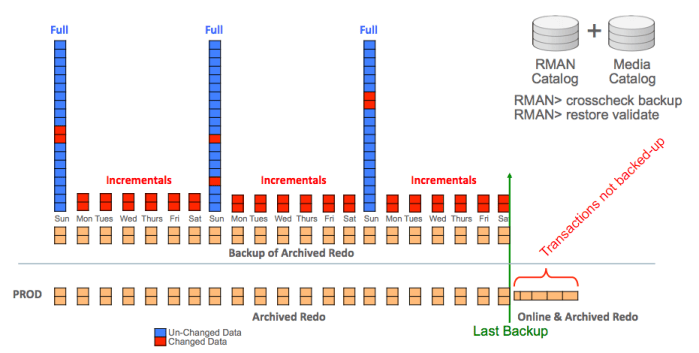
The Stage & Sweep Configuration involves RMAN writing the backup to disk, then the Media Manager is used to “sweep” that data to whatever storage device it is using (disk, tape or VTL). The disk staging area should be sized large enough to contain at least 2 full backups, all associated incremental backups, plus all associated redo.  The WFDDI (Weekly Full Daily Differential Incremental) will give this configuration:

Screen Shot 2018-02-27 at 2.05.34 PM

The above diagram shows space for 3 weekly full backups, plus all intervening incrementals and archived redo.  The resulting RECOVERY WINDOW is 2 weeks (from disk) because the oldest backup will be deleted before running the next backup.  Older backups can be stored only on the Media Manager, but a double-hop will be required during recovery using any backups coming from the Media Manager.

A Double Hop Restore is required in the Stage & Sweep configuration for cases where the needed backup is not on disk in the staging area.  The Media Manager stores the data in it’s own proprietary format, and RMAN cannot access those backups directly.  The Media Manager must retrieve the needed backups and write them back to the staging area before RMAN can access those backups.

Recovery from Full + Incrementals

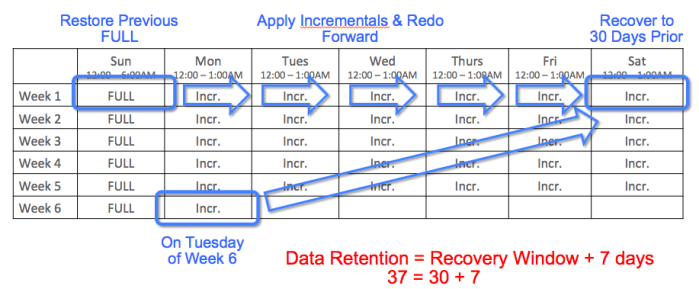
The most common backup strategy with RMAN Backup Sets is Weekly Full Daily Differential Incremental (WFDDI).  Some customers still use Daily Full (DF) backups for smaller databases, and lower Recovery Windows.  The following calendar shows a 30-day Recovery Window, which requires 37 days data retention:

Screen Shot 2018-02-26 at 12.27.27 PM

The “rule of thumb” for performance using WFDDI is that end-to-end recovery will be 2X longer as compared to recovery using a Daily Full (DF) strategy.

HA/DR and Backups

Note that Oracle’s MAA (Maximum Availability Architecture) team specifies that HA/DR (High Availability and Disaster Recovery) solutions should be used in conjunction with a backup/recovery solution.  Requirements for “instantaneous recovery” (low Recovery Time Objective) should be addressed through a DR solution such as Oracle Data Guard or Oracle Golden Gate.  Requirements for preventing system downtime should be addressed through HR technologies such as Real Application Clusters (RAC).  Backup/Recovery is distinctly different from HA/DR, and allows a system to be recovered BACKWARD in time to a prior point.

Low RPO Requirements

It’s important to note that Oracle’s Zero Data Loss Recovery Appliance (ZDLRA) can be used to deliver extremely low RPO (Recovery Point Objective) requirements in cases where RTO (Recovery Time Objective) is not as stringent.  As noted previously, a Disaster Recovery (DR) system using technologies such as Oracle Data Guard and/or Oracle Golden Gate is the recommended method for delivering low RTO.  Prior to the advent of ZDLRA, RTO and RPO were essentially linked and were addressed together.  We are now able to address low RPO requirements separately using ZDLRA, reducing the operational complexity of recovery in cases where time is not as critical.

RMAN Incremental Merge

The RMAN Incremental Merge feature was introduced in the Oracle10g release in 2006. This feature allows customers to create an IMAGE COPY backup of a database, then update that image copy using incremental backups.  Another way to describe this feature is “Incrementally Updated Image Copy” backups.  The image copy is updated as of a specific point in time.  Storage snapshots can then be added to this capability to provide recoverability to multiple points in time.

Screen Shot 2018-02-28 at 12.20.22 PM

The RMAN catalog tracks the original image copy, along with each incremental that is executed.  Snapshots of the Image Copy are taken at various intervals, and these are done outside the control of RMAN.

Image Copy Location – Separate storage is used to hold the image copy.

CPU Stealing – The merge operation is performed using “CPU Stealing” from the production database server.  The production database server executes an incremental backup on the database, then applies those changes to the image copy.   This places additional load on the database server for the duration of the Incremental Merge process.

Incremental Merge Performance is affected by the fact that changes to the database tend to involve random I/O.  Performance of the incremental merge operation can be increased only by putting the image copy on faster storage.

The “Switch to Copy” capability of Incremental Merge is only useful if the image copy is stored on the same tier of storage as the primary database.  We typically put backup on lower tiered (less costly, less performant) storage than the primary database.  However, if that backup will potentially BECOME the primary database by doing “switch to copy”, the storage needs to be of similar performance class.

Incremental Merge Recovery is Manual

Using an RMAN Incremental Merge with Snapshots, all recovery is manual.  Guided Recovery in OEM and Oracle’s Recovery Advisor aren’t used.  It’s possible to mitigate this somewhat by registering the snapshots in the RMAN catalog.  Third party tools that implement this method typically provide some tooling to assist Database Administrators with recovery, but those tools are not as widely used in the industry.

ZDLRA – the 5th Method

Oracle’s Zero Data Loss Recovery Appliance is nominally based on RMAN Backup Sets, but it’s a distinctly unique solution.

screen-shot-2017-01-03-at-3-29-11-pm


Any Oracle version and any platform (those currently supported as of this writing, meaning 10g and above) can be configured to use the Recovery Appliance.

An Initial Full (LEVEL0) Backup is used to seed the recovery appliance.  That initial full backup effectively does not exist after a while, as blocks belonging to that backup are eventually purged.

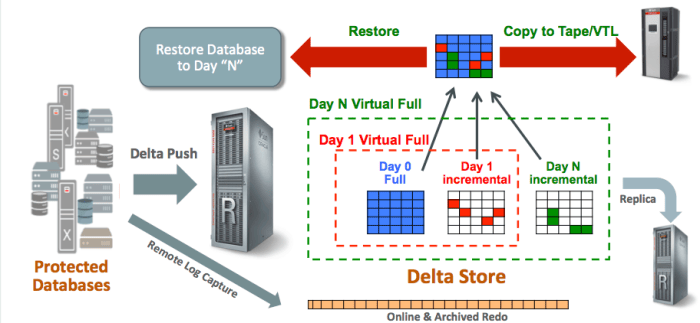
Delta Push uses the RMAN Incremental API to push changes from the database to the Recovery Appliance.  While this uses the syntax of a conventional RMAN LEVEL1 (incremental) backup, it is functionally quite different.  Each Delta Push is automatically transformed into a Virtual Full backup.

Virtual Full (LEVEL0) Backups appear in the RMAN catalog after the contents of each Delta Push are processed.  There is a Virtual Full created for the initial physical LEVEL0, as well as for each subsequent Delta Push.

Real Time Redo Protection uses the Data Guard API to protect the leading edge of the redo stream.  Redo is transmitted asynchronously to prevent the Recovery Appliance from becoming a bottleneck.  The Recovery Appliance ensures Zero Loss up to the last transmitted SCN in this configuration.  ZDLRA is supported for use with a Far Sync Server to allow synchronous capture of redo changes without imposing a bottleneck across multiple systems.

ZDLRA Benefits

The Zero Data Loss Recovery Appliance provides a number of unique benefits compared to other solutions on the market.

screen-shot-2016-12-25-at-4-18-12-pm

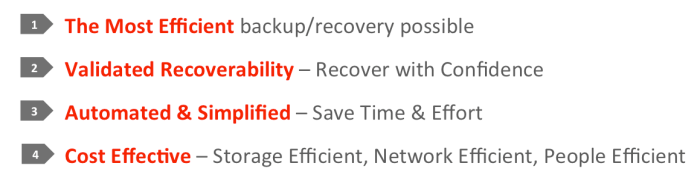
Efficiency of ZDLRA begins with impact on the production database servers, then extends through the network and into the space required on ZDLRA.  Changes are pushed to ZDLRA using the Delta Push process (the most efficient possible), and those changes are automatically converted into Virtual Full Backups.  The Virtual Full Backups are then used during recovery, making the recovery process more efficient as well.

Validated Recoverability is a key benefit of ZDLRA.  Backups are validated proactively rather than during recovery.  Customers can recover with confidence knowing the backups have been validated.  The Recovery Appliance will attempt to automatically resolve validation failures (such as redo log gaps), and will report validation failures if they cannot be resolved automatically.

Automation & Simplicity is another key benefit of ZDLRA.  The Recovery Appliance uses familiar tools and the full range of automation capability (such as Guided Recovery) that is already built into the Oracle ecosystem (Database, RMAN, OEM, etc.).  Backups are dramatically simpler because each database simply does a Daily Delta Push rather than complex scheduling of weekly full backups that might contend with application processing.

Cost Effectiveness is extremely important for any backup/recovery solution, and ZDLRA is the most cost-effective solution on the market.  ZDLRA requires the least amount of storage space possible because of the change-based design that directly extracts changed blocks through the Delta Push process.

Space Usage Comparisons

All 4 of these solutions have a variety of advantages and disadvantages, but we should first compare the based purely on the amount of storage space required.

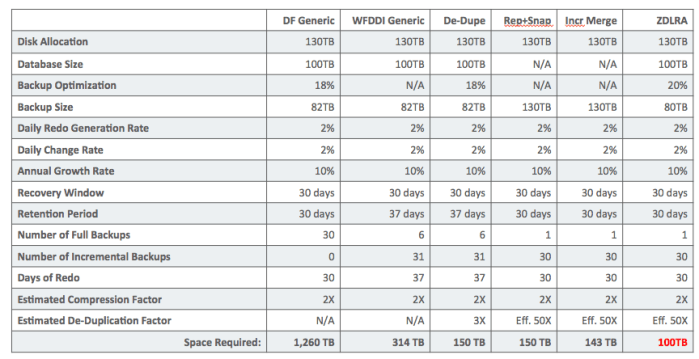
While all of these solutions provide dramatic space savings over generic solutions, ZDLRA provides the greatest storage savings of all.  The most dramatic saving comes from the use of RMAN Incremental Backups (WFDDI) as opposed to Daily Full (DF) backups.  As shown in this example, ZDLRA requires approximately 1/3 less storage space than all of these other solutions.

Screen Shot 2018-02-28 at 1.33.47 PM

As shown in the table above, with a given database size of 100TB, and with the same redo generation rate, change rate, recovery window, etc. ZDLRA requires the least amount of space.

DF Generic means Daily Full backup to general purpose storage.  Notice that the “recovery window” is equal to “Retention Period” since full backups are taken daily.

WFDDI Generic shows the impact of implementing a WDFFI (Weekly Full Daily Differential Incremental) strategy.  This is a dramatic 4X savings in space as compared to Daily Full backups.  Notice that the “Retention Period” is 7 days longer than the “Recovery Window” because this scenario uses a Weekly Full backup.

De-Dupe takes the WFDDI strategy and adds de-duplication storage.  Daily Incrementals and REDO logs do not contain duplicates by definition (these contain all unique data).

Rep+Snap shows the use of storage replication with snapshots on the replica side only.  This method uses a full size replica of the database, then adds daily snapshots to capture changes.  The changes are space efficient, but this solution requires a full sized copy (replica) of the database.

Incr. Merge shows the storage required for an RMAN Incremental Merge solution with snapshots.  As with the replication + snapshot method, RMAN Incremental Merge uses a full sized Image Copy of the database, with the same sized disk allocation.  Changes contained in snapshots are space efficient, but the fully provisioned database size consumes the same amount of space as on production.


De-Duplication in ZDLRA

Customers often ask whether ZDLRA has de-duplication capabilities, and (if so) how ZDLRA performs de-duplication.  This blog post will explore this question and explain how de-duplication works inside of ZDLRA.

Change-Based – The Opposite of De-Duplication

ZDLRA is change-based, which is the opposite of de-duplication.  The primary purpose of the Oracle database engine (any database engine, in fact) is to track and manage changes to data.  ZDLRA essentially taps into those change management mechanisms of the Oracle database to capture and store changes.

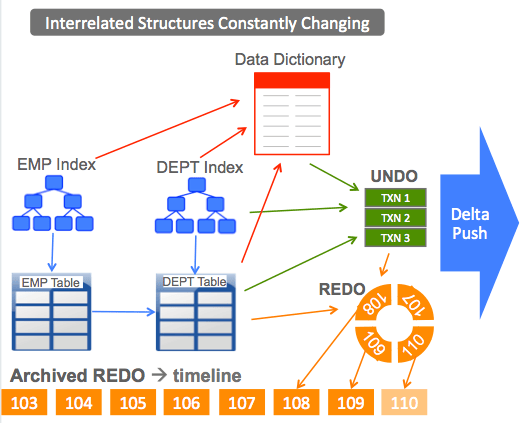
An Oracle database is comprised of interrelated data structures that are constantly changing.  Data in a Relational DBMS is organized into tables and tables have relationships between them.  Each table might have one or more indexes, and the pointers in each index are pointing to rows in the corresponding table.  These structures are represented in the Data Dictionary, which is tightly related to all of the tables, indexes, and other structures in the database.

The following diagram shows an extremely simple database comprised of 2 tables (EMP and DEPT) and 2 indexes.  Small production databases might have several hundred tables, and large databases might have TENS of THOUSANDS of tables, indexes and other data structures.

Screen Shot 2018-02-21 at 9.08.33 AM

Oracle databases are constantly changing.  The only way to “quiesce” an Oracle database is to force all users to disconnect and shutdown the database.  As long as the database engine is running, the data it contains will be changing.  Changes in the database (made by transactions) are written into the REDO log.  The opposite of those changes are written into an UNDO “log” in case those changes need to be reversed.  Changes to the database are sent to ZDLRA using the Delta Push process.

Delta Push = Virtual Full Backup

ZDLRA uses the RMAN “incremental backup” API to capture changes on the source database.  While this incremental backup might appear to be the same as a conventional incremental backup, it is fundamentally different in ZDLRA.  When a DELTA PUSH is executed, the results are automatically transformed into a VIRTUAL FULL backup in what is known as the Delta Store inside of ZDLRA.

Creation of the Virtual Full backup also means that changes in the database are tracked from the previous Virtual Full instead of the last Physical Full backup.  Although ZDLRA makes use of the RMAN INCREMENTAL backup API, the results are quite different.  ZDLRA is often referred to as an “incremental forever” solution, but that terminology has a certain connotation.  Other products on the market might appear to be similar (such as solutions based on the RMAN Incremental Merge feature), but they are based on a fundamentally different operating principal.

I prefer to use the term Delta Push instead of “incremental forever” because ZDLRA is vastly different than anything else on the market.

Delta Store – A Database of Block Versions

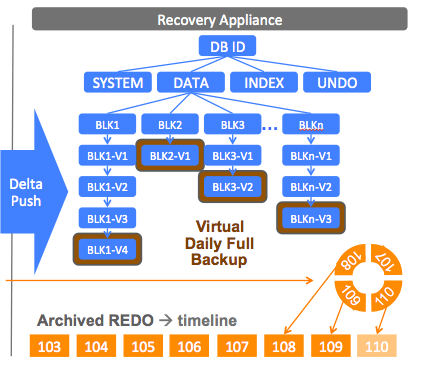
The Delta Store within ZDLRA is a database containing versions of database blocks.  Every Oracle database  is comprised of tablespaces such as SYSTEM, DATA, INDEX, UNDO, etc.  Customers can add their own tablespaces and name them as desired to organize data within the database.  Each tablespace is comprised of many blocks.  ZDLRA captures a copy of each block and arranges that block into the hierarchy.

Screen Shot 2018-02-21 at 8.52.06 AM

Each Delta Push sends the latest version of each changed block.  Those changed blocks are indexed into the Delta Store and combined with previous un-changed blocks to form a Virtual Full Backup.

Frequency of Delta Push (Daily)

The vast majority of databases will push changes to ZDLRA once per day, resulting in a Daily Virtual Full Backup.  Some databases might have extremely HIGH or LOW change rates and customers might want to use more frequent or less frequent Delta Pushes on those databases.  However, these will be extremely rare circumstances and the vast majority of databases will simply use a Daily Delta Push.

Initial Physical Full

ZDLRA begins with a PHYSICAL FULL (LEVEL0) backup of each database.  That full backup is arranged into the Delta Store and serves as the basis for all Virtual Full Backups moving forward.  Some Oracle database blocks will never change for the life of the database, while other blocks change continuously.  Over the course of time, many block versions from the initial LEVEL0 will be purged when the Recovery Window is reached.  The initial physical full essentially doesn’t exist any longer, although the oldest Virtual Full will be available in the Delta Store.

Fast Incremental (Block Change Tracking)

We recommend using the “Fast Incremental” feature of the Oracle database, which is also known a Block Change Tracking (BCT).  With Block Change Tracking, the Oracle database records all blocks that have changed since the last backup.  BCT tracks changes since the last VIRTUAL FULL backup when ZDLRA is being used.  The BCT pointers are reset each time RMAN connects to ZDLRA and performs an implicit SYNC operation.

De-Duplication (Subsequent Physical Full)

De-Duplication occurs in ZDLRA whenever a subsequent physical full backup is executed. It is possible (but certainly not recommended) to execute subsequent full backups to ZDLRA after the first physical full.  ZDLRA will identify the changed blocks and insert them into the hierarchy in the Delta Store, discarding all of the un-changed or “duplicate” blocks.

The “Global” De-Duplication Question

As shown in the above diagram, ZDLRA organizes backups database under the DBID (Database Identifier) for each database.  This obviously means that data from one database will not be associated with and de-duplicated against data contained in a different database.

Database Blocks – Data within an Oracle database is contained in database blocks.  If the same data is insert into 2 separate databases, the physical blocks are virtually guaranteed to be different.  Each database block contains a row directory, interested transaction list (ITL), header metadata, footer metadata, etc.  Each database block records the SCN (System Change Number), which is unique to a particular database.  Two physically separate databases might contain the same logical data, but the physical database blocks will be different at the bit/byte level.

Cloned Databases – The only way to generate duplicate physical blocks across 2 or more databases is to “clone” the database.  A cloned database is a physical copy of a database, but a different DBID is assigned to that database.  Backups of cloned databases will contain physically duplicate blocks of data.

Sparse Clones – Oracle supports what are known as “sparse clones” of databases using SPARSE disk groups in ASM (Automatic Storage Management).  In a sparse clone configuration, there is a “master” copy of the data with multiple clones.  Each clone writes changed blocks (different from the master) into a SPARSE disk group.  The SPARSE disk group contains only the changes for a particular clone.  The database engine reads from the “master” or from the “cloned” blocks as necessary.

Sparse Backups – The next logical step in the evolution of sparse clones is to have Sparse Backups.  Sparse backups only contained the uniquely different (changed) blocks for the clone.  The sparse backup is merged with the master copy to generate a physically unique database upon restore.  ZDLRA currently supports backup of sparse clones, but these are done as physical backups.  Oracle can discuss future plans in this area under NDA (non-disclosure agreement).

As we can see from the discussion above, “global” de-duplication, or de-duplication across multiple databases will only occur in a TEST/DEV environment.  It’s virtually impossible to have physically duplicate blocks across multiple production databases, even if those databases contain the same data in tables and indexes.  Oracle’s direction is the use of sparse clones for TEST/DEV environments, extending the sparse clone capability into sparse backups.

Change Rate vs. De-Duplication Factor

The rate of change in an Oracle database is generally expressed in terms of a percentage, meaning the changed blocks as a percentage of total blocks within the database.  For any large population of Oracle databases, the AVERAGE change rate will be in the range of 2% to 4% each day.  The average change rate typically varies by industry.  Industries with longer data retention periods (retention of data within the database) will have databases with a low daily change rate compared to industries with shorter data retention.  Each company might have specific databases with higher or lower than average daily change rates, but such outliers are not common across a large population of databases.

De-Duplication is typically expressed as a factor, such as 3X or 4X de-duplication.  A database with a 3X de-duplication factor is the same as a 33% change rate.

Changed Blocks vs. De-Duplicated Segments

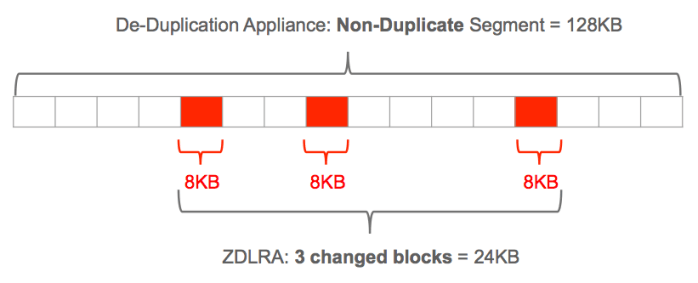
The Oracle database engine tracks and manages changes to blocks of data.  The typical Oracle database block is 8KB in size.  By contrast, de-duplication storage appliances process data in larger “segments” of data, typically at 128KB in length.  Each 128KB segment typically contains 16 Oracle database blocks (assuming 8KB block size).

The typical Oracle database with an OLTP workload will have changes that are fairly distributed across the database from a physical perspective.  Data Warehouse databases tend to have more changes that are concentrated into contiguous blocks.  Large sequential data loads will be more tightly sequenced into blocks on disk, whereas INDEX changes will be more distributed.  The following diagram shows 3 changed blocks (8KB each) within a string of 16 blocks (128KB total segment length).

Screen Shot 2018-02-21 at 11.47.35 AM

Using a de-duplication appliance, the entire string of 128KB will be stored as a non-duplicate segment, while ZDLRA will store only the 3 changed blocks (24KB).

Variable Length De-Duplication

Some de-duplication vendors support what is known as “variable length” de-duplication, which simply means the segment size is tunable.  For de-duplication to work, the segment size must be consistent.  For example, a string of data 64KB in length logically cannot equal a 128KB string of data.

We have tested de-duplication of Oracle backups using 8KB segment lengths.  While tuning a de-duplication appliance to use an 8KB segment size will equal the effective de-duplication rate of ZDLRA, we have found that performance suffers greatly.

ZDLRA is Cost Effective

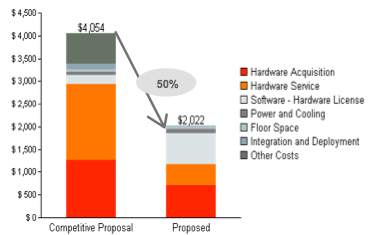
The efficiency of ZDLRA makes it more cost effective than other solutions on the market. ZDLRA only captures the specific CHANGED data each day, resulting in the smallest possible volume of data stored.  ZDLRA is not the lowest cost on the market when measured by cost per terabyte, but ZDLRA needs fewer terabytes than other solutions. In most cases, ZDLRA needs 1/3 less storage space than competing products on the market, regardless of the competing product architecture.  Less space means lower cost as we see in the following example:

Screen Shot 2018-02-21 at 11.49.13 AM

Less space means a lower acquisition cost (purchase price), lower cost of services such as support, etc.  Less disk space means less physical space in the data center, lower costs for electrical power, etc.

Solutions such as Replicated Snapshots and De-Duplication appliances simply cannot match the space efficiency of ZDLRA, giving ZDLRA the edge from a cost standpoint.  ZDLRA then offers numerous advantages beyond simple storage savings and cost, driving more value than we covered in this blog post.


Data Warehouse for Everyone

Oracle’s new Autonomous Data Warehouse Cloud is democratizing the world of Data Warehousing so that literally anyone can gain access to industrial strength data analytics.

Gone are the days when millions of dollars and months of time are needed to setup a Data Warehouse using Teradata, Exadata, or some other system just to gain insight into your business data. Users can now easily and quickly gain access to the fastest, most secure, and most capable analytic platform in the Cloud.

Autonomy = Eliminating DBA Tasks

Oracle’s Autonomous Data Warehouse Cloud eliminates back-end DBA tasks such as software installation, patching, upgrades, system optimization, system tuning, database backup, and other mundane but time consuming tasks that don’t drive business value. Oracle has taken control of the back-end system and turned it over to Artificial Intelligence algorithms, allowing database Administrators to focus on more high value work such as data modeling, data architecture, and optimizing business processes.

Database Administrators should NOT worry about Autonomous Data Warehouse making their job obsolete. Oracle has been automating administrative tasks for decades, making the role of DBA’s even more valuable. DBA’s will be able to put even greater focus on business processes, data modeling, data architecture, and performance of business processes rather than mundane tasks like patching software.

One Warehouse, Many Users

In typical Oracle parlance, one Data Warehouse can serve many users who often share data, sections of data, or what is known as subject areas within the same Warehouse. Sales, Marketing, Customer Service, and other users can have their own separate data within the Warehouse, but can also easily share data between them.

Fast & Flexible Data Loading

Oracle Autonomous Data Warehouse Cloud supports all of the leading data loading or ETL products that customers are familiar with. The following 3 sources can be used for loading data directly into your Data Warehouse:

  • Load from on-premise sources
  • Load from Amazon Cloud Storage
  • Load from Oracle Object Cloud Storage

Autonomous Data Warehouse also allows data to be loaded using simple SQL statements with data in these sources defined using what are known as external tables. For extremely large volumes of data, Oracle also provides data transport services.

No matter which method you choose for loading data, Autonomous Data Warehouse makes it fast, easy, and secure.

Directly Access External Data (Amazon S3, etc.)

Autonomous Data Warehouse provides the fastest access to data that has already been loaded into tables within the Warehouse, but users can also directly query data in Amazon S3, in Oracle Object Cloud Storage, as well as from on-premise data sources.  These external data sources are mapped as external tables, giving users direct access to that data using simple SQL statements.

No Indexes to Create

Autonomous Data Warehouse Cloud greatly simplifies administration by eliminating the need for users to create indexes. ADWC does have indexes, but users don’t need to create them. ADWC provides excellent performance even for single row queries.

Internal Performance Technologies

Automated Data Warehouse delivers unsurpassed performance through several technologies including the following:

  • Automatic Multi-Level Caches
  • Active Storage
  • Automatic Data Indexing
  • Automatic Optimizer Statistics

Users need not be concerned with these technologies beyond knowing they exist and give excellent performance.  Prior to the advent of the Autonomous Data Warehouse Cloud, database administrators would often spend countless hours using manual methods to tune what is now done autonomously.

Automatic Data Caches

One mechanism used by ADWC is a multi-level system of data caches. As data is used more and more often, ADWC stores or “caches” that data in faster layers of caches. Data automatically moves from spinning disk to Flash, to memory in the Active Storage layer, to DRAM caches in the CPU processing layer. Data is automatically brought into In-Memory data stores, and results are even cached to speed later access to the same data.  The size and uses of each cache is handled autonomously by ADWC.

Active Storage

Data in the Autonomous Data Warehouse is housed in storage, of course, but not in convention disk storage as with other Cloud services.  Instead, ADWC uses an “active storage” layer, which transparently brings additional processing power to handle user queries without any user effort.

Active Storage in the Autonomous Data Warehouse simply makes warehouse queries run faster without any user intervention or performance tuning. Exadata users know this as SQL Offloading, but it simply means that queries run faster by sending query work down to the storage layer for processing.  This is a time-tested approach in computer science, shipping processing logic to the data, rather than shipping data to the processing logic.  Whenever processing happens closer to the data (without moving the data), users simply see faster processing.

Automatic Data Indexing

Anyone who knows even the basics of databases and data warehousing knows that indexes make data access faster. People often wonder if Autonomous Data Warehouse doesn’t allow users to create indexes, how can it possibly be fast? The simple answer is that ADWC does have indexes, but they are created internally and automatically.  For example, ADWC uses a feature pioneered in Exadata called “Storage Indexes” that automatically creates indexes in the Active Storage layer on ADWC.

Automatic Optimizer Statistics

Users of conventional Oracle Data Warehouses on Exadata and other platforms might have heard about optimizer statistics from their DBA.  Optimizer statistics can be difficult to manage and often have a critical impact on performance of business processes.  The Autonomous Data Warehouse automates the collection and management of optimizer statistics to ensure optimal performance.

Pay as You Go – Compute vs. Storage

Customers pay for storage space on the Autonomous Data Warehouse Cloud Service in increments of 1TB. Compute power is charged on an hourly basis by the OCPU, and can be easily scaled up or down as needed using. Customers can completely TURN OFF the compute power if it’s not being used (such as during off-hours, on a weekend, etc.).

Encrypted by Default

Autonomous Data Warehouses are encrypted by default, providing protection for user data regardless of source or sensitivity. Oracle has always been a leader in data security since its inception, and those security technologies are built into the Autonomous Data Warehouse Cloud.